Every final build of PLI Labs on Tesla V100 (Volta, sm_70) cards: its link, what it runs on, and five lines of numbers. Each build is described on its own; depth is on its own page under optimizations/ and in its repository. All serve DeepSeek-V4.1-Flash-1017 (40 layers, 384 routed experts per layer, the DSpark drafter, the Engram memory).
Every number is MEASURED on our hardware with its date, power limit and clock ceiling, unless it says UPSTREAM (someone else’s, linked) or ESTIMATE (arithmetic). “Quality not established” means no accuracy test has run on that configuration. tok/s is tokens per second; “prefill” is prompt reading; the KV cache is what lets a request hold a long context.
Volta 12X AmPLIfy
Repository: https://github.com/ProprietaryLegal/Volta-12X-AmPLIfy-DeepSeek-V4.1-Flash-1017-NVFP4-12xV100-SXM2-PP3xTP4 · its optimizations
Every routed expert at NVIDIA’s NVFP4 precision, all 15,360 in card memory. MEASURED 2026-11-17 and early 2026-11-18, clock ceiling 1,477 MHz.
| What | Figures |
|---|---|
| Hardware | 12x V100-SXM2-32GB on three NVLink boards; three pipeline stages of four tensor-parallel cards (layers 0-13, 14-27, 28-39) |
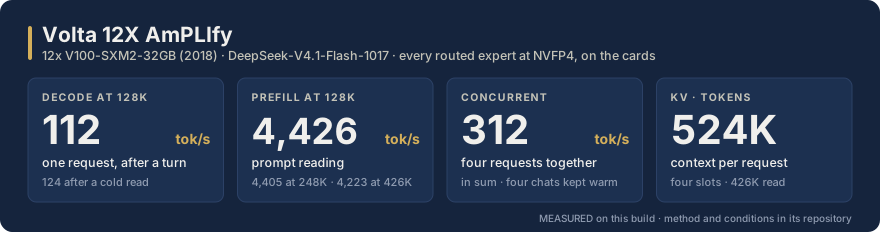
| Speed | Decode, one request: 128.1 tok/s on fresh text, 176.6 on a copying task (150 W); 129.7 and 179.2 at 200 W (one run). Prefill at 200 W (one run each): 3,850 tok/s at 61K tokens, 3,833 at 93K, 3,316 at 248K, 2,454 at 426K |
| Context and KV cache | 524,288 tokens per request. On a chat of about 128,600 tokens, a turn that adds 880 tokens reaches its first token in 1.24 s; adding 4,200 tokens, 3.75 s. Decode round 28.1 ms at 128K of context (26.25 ms on a short chat) |
| Concurrency | Four slots (four chats kept warm). Four requests together: 306.6 tok/s on fresh text, summed over the requests (242.6 by wall clock), 453.4 on copying tasks. A pipeline step carries one request, so throughput rises only up to three at once |
| Accuracy | The experts are NVIDIA’s NVFP4 pack, value-equal to DeepSeek’s official experts (UPSTREAM). Against an all-native reference: first divergence after a median of 208 tokens; mean absolute log-probability difference 0.0090. Answer quality in use: not established |
Volta Max uPLIft
Repository: https://github.com/ProprietaryLegal/Volta-Max-uPLIft-FP4-DeepSeek-V4.1-Flash-1017-NVFP4-8xV100-SXM2-PP2xTP4 · Hugging Face package, 556 GB · its optimizations
As much of the routed work at NVIDIA’s NVFP4 precision as fits on eight cards, every routed expert on the cards. MEASURED 2026-11-13 (close-out bench, two-slot default, cards at the default 300 W limit, clock ceiling 1,530 MHz) unless the row gives another date.
| What | Figures |
|---|---|
| Hardware | 8x V100-SXM2-32GB on two NVLink boards; two pipeline stages of four tensor-parallel cards. Host RAM 1 TB |
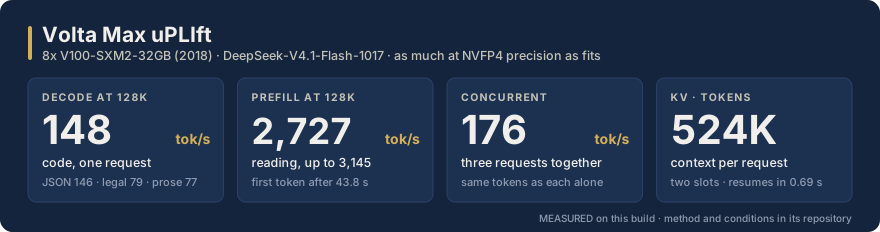
| Speed | At 128K of context: decode 147.9 tok/s on code, 145.5 on JSON, 79.1 on legal text, 76.9 on prose. Short sets: 117.7 tok/s general, 94.7 legal-style. Prefill 2,727 to 3,145 tok/s at 128K and 2,876 to 3,132 at 256K; first token after 43.8 s at 128K |
| Context and KV cache | 524,288 tokens per request. A follow-up after a changed reply resumes from a snapshot: first token 0.69 s where a cold read takes 31.0 s at 100K tokens |
| Concurrency | Two slots by default, one and three as options. Two requests together 158.7 tok/s in total; three together on three slots 176.2. Every request gave the same token ids as the same prompt alone |
| Accuracy | First release (one slot, native prompt reading), 2026-11-11, rules fixed before any capture: the same next token as NVIDIA’s NVFP4 pack on 95.1 % of compared tokens; KL divergence from it 0.079 nats; 83.6 % on 513 MMLU questions. The default since 2026-11-12 (two slots, fast prompt reading): quality not established |
Volta sPLIt
Repository: https://github.com/ProprietaryLegal/Volta-sPLIt-DeepSeek-V4.1-Flash-1017-8xV100-SXM2-PP2xTP4 · Hugging Face card · its optimizations
The 1Cat-vLLM DeepSeek-V4.1 package (#1277, yangzhuxinyzx) ported to two boards, with ISTA-DASLab’s 2-bit GGUF and every expert resident on the cards. MEASURED 2026-11-05 (checkpoint build, one request at a time, thinking off, greedy, 150 W per card, clock ceiling 1,522 MHz).
| What | Figures |
|---|---|
| Hardware | 8x V100-SXM2-32GB on two NVLink boards; two pipeline stages of four tensor-parallel cards; 251 GB of host RAM for the Engram tables |
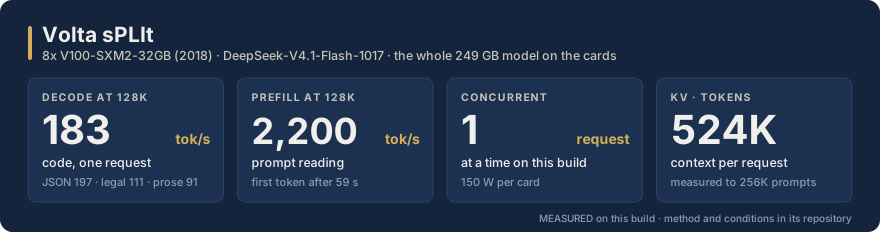
| Speed | At 128K of context: decode 182.8 tok/s on code, 196.5 on JSON, 110.9 on legal text, 91.1 on prose. At 1K: 215.0 on code, 117.6 on legal text. Prefill 2,198 to 2,220 tok/s at 128K; first token after 59.2 s at 128K, 17.2 s at 32K |
| Context and KV cache | 524,288 tokens per request; KV pool 2,076,870 tokens. Needles found at about 450K and 498K tokens: 6 of 6 in 4 of 4 runs |
| Concurrency | One request at a time. Three chat slots (since 2026-11-11) keep three chats’ caches: a return to a chat reaches its first token in 0.57 to 0.88 s where a re-read took 20.6 to 49.2 s |
| Accuracy | LegalBench 0.716 balanced accuracy (22 tasks); MMLU-Pro 79.9 % (700 items); HumanEval+ 89.6 %. The same next token as the original model 89.0 % of the time on a general panel, 92.5 % on a legal panel |
Volta Full NVFP4
Repository: https://github.com/ProprietaryLegal/Volta-Full-NVFP4-DeepSeek-V4.1-Flash-8xV100 · its optimizations
Every routed expert at exactly NVIDIA’s NVFP4 precision on eight cards; the experts that do not fit are read from pinned host RAM over PCIe. Built as an all-NVFP4 output to check other work against. MEASURED 2026-11-09, clock ceiling 1,522 MHz.
| What | Figures |
|---|---|
| Hardware | 8x V100-SXM2-32GB on two NVLink boards; two pipeline stages of four; about 101 GB of experts in host RAM (ESTIMATE) |
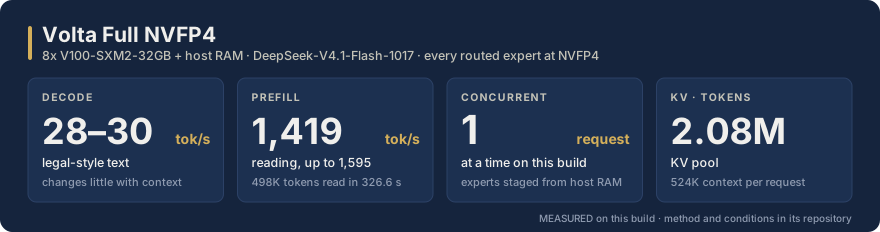
| Speed | Decode 28.2 and 30.2 tok/s on a legal-style short set (two runs), 18.8 and 20.1 on a general set; 31.5 tok/s after 106,531 tokens of context. Prefill 1,419 to 1,595 tok/s |
| Context and KV cache | 524,288 tokens per request; KV pool 2,076,870 tokens. A 498,099-token prompt read in 326.6 s with no out-of-memory error |
| Concurrency | One request at a time |
| Accuracy | 44,696,862,720 folded expert values checked bit-equal to the NVFP4 formula. 83.8 % on 513 MMLU questions (2026-11-11) |
Earlier V100 builds
| Repository | What it is |
|---|---|
| deepseek-v4-flash-v100 | DeepSeek-V4-Flash on eight V100s with llama.cpp (July 2026): 12.2 tok/s generation, 209 tok/s prefill at 8K (MEASURED, 245 W per card); the root cause and fix of a silent quantized-KV corruption; and the interim DeepSeek-V4.1 results of 2026-11-01 on the EXL3 engine |
Volta sPLIt, previous-build/ |
The first DeepSeek-V4.1 build on eight cards, on Phil Tompkins’ EXL3 engine (2026-11-01): 42 to 46 tok/s decode by its own method |
| deepseek-v4.1-v100 | A fork of philbert440’s engine snapshot. Phil Tompkins’ work |
| GLM-5.3-Flash NVFP4 on eight V100s with 1Cat-vLLM (September 2026; no repository of its own) | The first fast large-model build on these boards: about 49 tok/s without a drafter, 78.8 to 113.8 tok/s with the DFlash2 drafter on short prompts, 204,800 tokens of context (MEASURED; earlier builds) |
| swift-1.5-v100 | Swift 1.5 (a 27B model) on four V100s with the stock 1Cat-vLLM wheel: 247.7 tok/s decode at a 12K prompt (MEASURED) |
pli-labs, research/v100 |
The V100 research notes of June and July 2026 |
| Hugging Face deepseek-v4.1-flash-sm70, sm70-fp8-block32-kernels | The first twelve-card port (1Cat-vLLM #1031, October 2026; UPSTREAM in the pull request: 2.8 to 3.9 tok/s without CUDA graphs) and its FP8 dense kernels (#1021) |
What each of these found: optimizations/earlier-builds.md.
Mirrors we keep (other people’s work)
| Mirror | Original | Licence |
|---|---|---|
| ProprietaryLegal/1Cat-vLLM | 1CatAI/1Cat-vLLM, the Volta and Turing vLLM fork every build here runs on | Apache-2.0 |
| ProprietaryLegal/v100-skinny | dnv2003/v100-skinny, Dennis Vertzyas’ hand-written NVFP4 and FP8 kernels for Volta | MIT (kernels, docs), Apache-2.0 (fork patches) |
Sister work (not Volta)
DGX sPLIce runs the same model on two NVIDIA DGX Sparks with an x86 machine that holds the Engram tables and runs the drafter. A different chip (GB10) with its own repository; its measurement harness is dsv41-window-harness.
The hardware and the skill
What to buy to build one of these boards: hardware.md. The method that produced the builds, packaged for coding agents: PLI Volta Builder (front page, part 9).